Transformer Basics
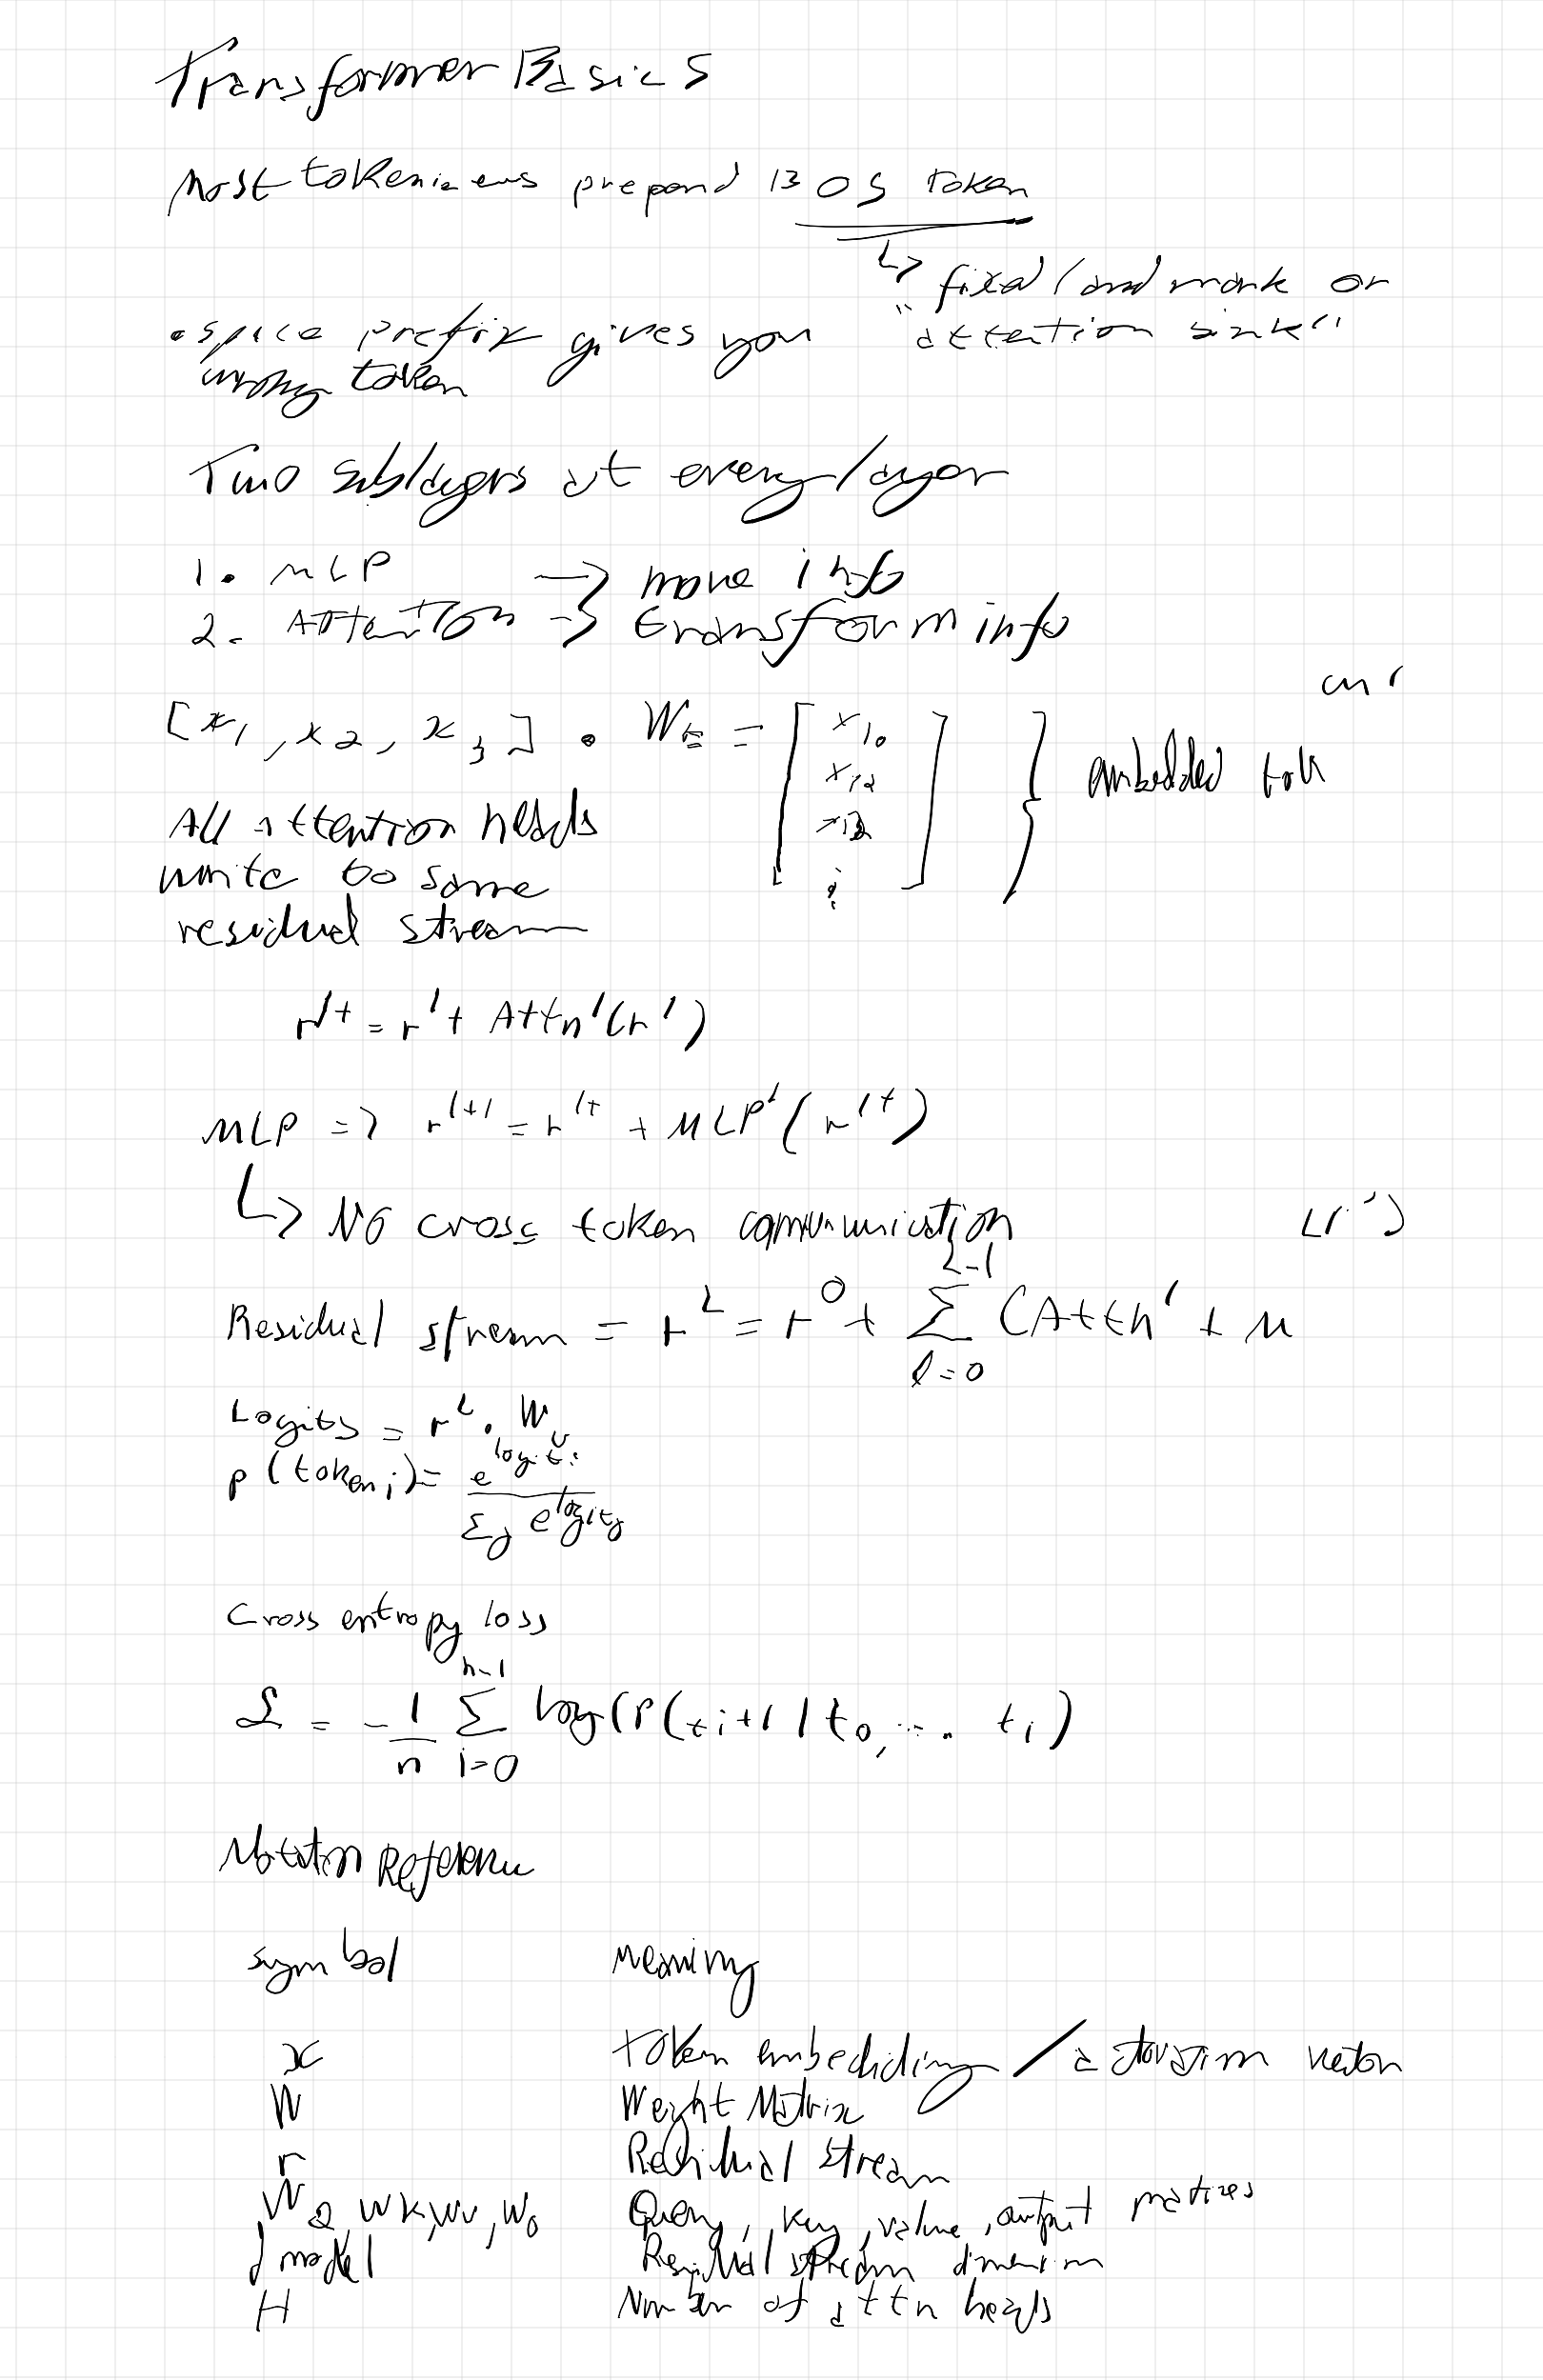
Most tokenizers prepend a BOS token.
- ↳ fixed landmark or “attention sink”
- space prefix gives you the wrong token
Two sublayers at every layer
- MLP → move info
- Attention → transform info
All attention heads write to same residual stream.
MLP ⇒
↳ NO cross token communication
Cross entropy loss
Notation Reference
| symbol | meaning |
|---|---|
| token embedding / a -dim vector | |
| weight matrix | |
| residual stream | |
| query, key, value, output matrices | |
| residual stream dimension | |
| number of attention heads |